Software engineering for biotech
For the team, that means bioinformatics pipelines that keep pace with sequencing output, analysis that produces defensible findings, and infrastructure that scales from a founding team's laptops to a platform investors and partners can rely on — often on a timeline set by the next funding round rather than the next planning cycle.
Software around the science
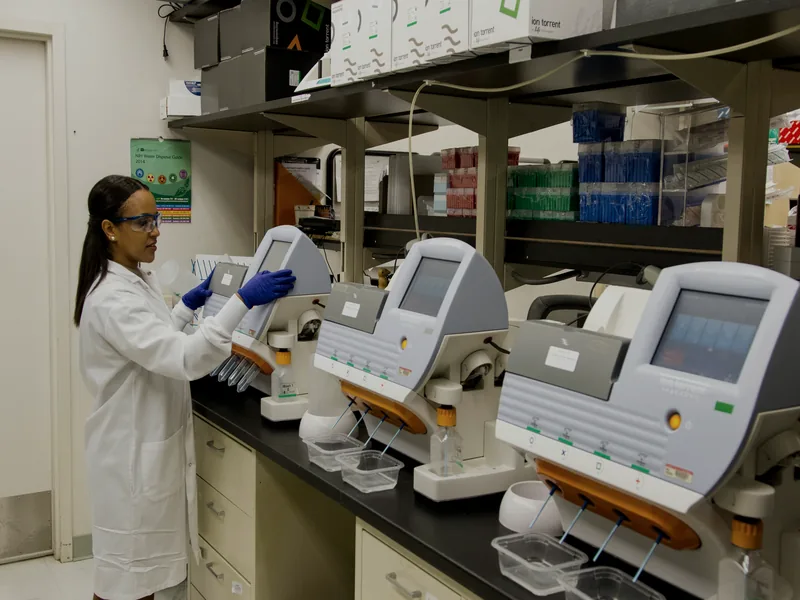
A biotech team is often strongest around the science and much thinner on the software around it. The first version of a pipeline is often written by the person who knows the assay or analysis best. That is fine until the data volume grows, another site starts running the same work, or someone needs to reproduce a result from eighteen months ago.
Sequencing output is a common point where this changes. Genomic datasets can reach hundreds of gigabytes per sample and terabytes per study. An analysis that once ran on a laptop becomes an infrastructure problem. BWA aligns reads, GATK calls variants, and SAMtools handles the files between them. The whole process has to run reliably across samples, on a cluster or in the cloud, without someone checking it overnight.
The requirements can change as the work moves toward a clinical claim or a partner programme. The software then has to produce the same result with the evidence behind it. At that point, validation, traceability and reproducibility become part of the software work.
Pipelines that depend on one person
The pipeline runs because one person knows which step to skip and which file sometimes needs fixing by hand. That knowledge has to move into the software. We put the workflow into an engine, pin tool versions in containers, define the inputs and outputs for each stage, and replay reference samples after changes. That leaves the team with a pipeline it can run without depending on one person's memory.
Statistical rigour under time pressure
A result has to hold up when a partner's scientists or a regulator reviews it. On the engineering side, that means keeping the reference version, analysis parameters and raw inputs fixed and recorded, and keeping a clear record of which inputs produced which output.
Scientific literature and internal research
A small team cannot keep up with everything published in a field. We make the material searchable and keep the source with the answer. The model is only one part of that system.
The transition to regulated
Once the work becomes regulated, the team needs to be able to answer basic questions about the system. What were the requirements? Where is the evidence? Who approved it? Can the result be reproduced? We bring validation into the build rather than adding it after study data is already in the platform.
Nextflow, WDL or Snakemake, whichever the team already uses. For new pipelines, we recommend Nextflow because nf-core gives a tested starting point and the same pipeline can run on a laptop, an HPC scheduler or in the cloud.
Web applications, APIs, reference databases and job orchestration, built as part of the engineering team where that is what the company needs.
Requirements linked to tests, results retained as evidence, and a reference set replayed as the software changes.
On a Veeva Vault migration for a biotechnology company running clinical studies, more than 10,000 documents moved from AODocs with metadata mapped field by field. There was a trial migration first, hash verification on every file, and the audit trail was retained.
On an NGS mutation calling platform, a Cypress framework covered 98 percent of frontend workflows and every pipeline stage was validated programmatically.
Sometimes the pipeline already works but needs to run at scale. We add the reproducibility work, tests and documentation. Sometimes the science is there and the application, APIs and orchestration still need to be built. For a new assay, we build the pipeline with validation included from the start.
Questions people ask
Do we have to change workflow engine to work with you?
No. A team running WDL keeps WDL. A team with years of Snakemake rules keeps Snakemake. For a new pipeline, we suggest Nextflow.
What does reproducible actually require?
Tool versions pinned in containers, defined inputs and outputs at every stage, reference samples with known results replayed after changes, and the raw inputs kept so an output can be traced back to the file that produced it.
When should validation start?
Before the platform starts carrying study data. Adding validation later is considerably more work.
Pipeline outgrowing the way it was first written?
Tell us what you run, where it runs, and what has to be reproducible.
Start a conversation